Author
Anju Khanna Saggi
Content & Media Relations
Published: 2025-10-29
Last updated: 2026-09-28
Root cause analysis starts from the simple idea that fixing what broke isn't the same as fixing why it broke. On site, especially in construction materials and heavy industry, the pressure is to fix things fast so there’s no delay in getting up and running as every stoppage means revenue walking out the door. But if the same issue keeps coming back and you keep "fixing" it, it's worth stopping for a minute to ask: are you actually solving the problem, or just patching it?
Root cause analysis (or RCA) is the discipline of finding out what caused the problem to happen in the first place, and why. It’s a structured way to dig deeper until you uncover what actually led to the event: the process gap, the training miss, the timing issue, or the flawed assumption that set it off.
When done right, RCA shifts your focus from firefighting to prevention. And in this article, we’ll go over the most important parts you need to know about root cause analysis.
Key takeaways
-
- Root cause analysis looks beyond the immediate fault to find the deeper reason a failure or incident occurred.
- The 5 Whys, Fishbone diagrams and Pareto analysis offer different ways to trace causes and prioritise problems.
- A reliable RCA is built on evidence, input from the people doing the work and a review of the full timeline.
- Corrective actions must address the underlying cause and be checked afterwards to confirm that they worked.
- Digital RCA tools and software keep evidence, investigations and follow-up actions connected, making lessons easier to apply across the operation.
Contact us
What is Root Cause Analysis (RCA)?
Root cause analysis is a structured way to find the real reason behind a problem, not just the surface cause. It’s about exploring why something happened until you uncover the deeper issue that made it possible in the first place. Think of it as the difference between mopping a wet floor and fixing the leaking pipe above.
Too often, operations settle for quick fixes such as replacing a failed sensor, adjusting a setting, or rewriting a procedure, without understanding why it failed. RCA forces you to dig below the obvious. At its core, root cause analysis is built on three principles:
- Base it on facts, not gut feeling. You gather real data for what happened, where, when, and under what conditions.
- Involve the people who know the work. The best insights come from operators, drivers, or maintenance techs who are closest to the job, and know the ins and outs of the operation.
- Look across the full timeline. Don’t get stuck at the moment something broke. Trace back what led to it from planning, to inspection, to operation.
Most common Root Cause Analysis Methodologies
A root cause analysis does not refer to a single method, but is rather used as an umbrella term that covers different schools of thought. The three most known and used RCA tools are the 5 Whys, the Ishikawa (Fishbone) diagram - also known as the 7M model, and Pareto analysis.
However, the point isn’t which root cause analysis methodology you use. It’s how you use it and whether you’re willing to go far enough to find what’s really broken in the system. A good root cause analysis doesn’t end when you find one answer. It ends when you understand why it happened in the first place.
The 5 Whys
The 5 Whys method is the simplest way to dig into a problem, and one of the most common ways to go about it. If you’ve ever been around a five-year-old, this will sound familiar:
- “Why did it stop?” - “Because the belt jammed.”
- “Why?” - “Because the roller seized.”
- “Why?” - “Because the bearing failed.”
- “Why?” - “Because no one greased it.”
- “Why?” - “Because the PM schedule was never updated.”
That’s the mindset. Keep asking until you hit the real cause, not just the first one that’s easy to name. Five questions is just a guide; sometimes you’ll find the root after three, sometimes you’ll need seven. What matters is persistence.
The Ishikawa (Fishbone) Diagram
The Ishikawa Diagram, often called a Fishbone because of its shape, helps visualize all possible causes that could lead to an effect or deviation. It’s structured around the 7M categories: Man, Machine, Method, Material, Measurement, Management, and Mother Nature (Environment).
This method shines when problems are complex or cross functional lines, for example, a recurring product defect, repeated equipment breakdown, or process bottleneck that doesn’t have one clear trigger. By mapping causes along the “bones” of the diagram, teams can see patterns they might otherwise miss.
It encourages a broad view: looking not only at what failed, but at the conditions, habits, and controls that shaped the event. It’s especially powerful when combined with factual field data such as photos, readings, or logs that keep the discussion grounded in reality.
Pareto Analysis
When a site has dozens of small issues, the hard part isn’t finding causes, it’s deciding which ones to fix first. That’s where Pareto Analysis comes in handy. Based on the 80/20 rule, it helps teams identify which 20 percent of causes are responsible for 80 percent of the impact, whether that’s downtime, safety deviations, or quality losses.
The method typically uses bar charts to show how often each problem occurs, so the biggest offenders stand out immediately. Pareto is best used early in an RCA program or when reviewing maintenance and incident data across several sites. It helps narrow the focus to where effort delivers the most return to turn “too many problems to handle” into a manageable list of priorities.
Root Cause Analysis example - Step by step
Let’s look at a root cause analysis example, of how it could work in practice. In this example, a conveyor belt at an aggregates plant keeps slipping and stopping production. The maintenance team has adjusted it several times, but the problem continues to reappear. To investigate further, the team uses the 5 Whys method.
Step 1: Define the Problem
First, the team describes the problem clearly:
Conveyor 3 has stopped four times in two months because the belt moved out of alignment, causing several hours of downtime.
This establishes what happened, how often it occurred, and how production was affected.
Step 2: Gather the Facts
The team reviews work orders and inspection records, examines the conveyor, and speaks with the operators. They find uneven wear on the belt, a worn tensioner, and no recorded tensioner inspections.
Step 3: Ask the 5 Whys
The team then traces the failure backwards:
- Why did the conveyor stop? The belt moved out of alignment.
- Why did it move? The belt tension was uneven.
- Why was the tension uneven? The tensioner was worn.
- Why had it not been replaced? Its condition was not checked.
- Why was it not checked? It was missing from the preventive maintenance checklist.
The slipping belt was the visible problem, but the underlying cause was a gap in the maintenance routine.
Step 4: Take Corrective Action
The team replaces the tensioner and realigns the belt. They also add tensioner checks to the maintenance schedule, set inspection intervals, and review similar conveyors for the same gap.
Step 5: Check the Result
Over the following weeks, the team monitors the conveyor to confirm that the fault does not return. If it continues running without further belt-alignment problems, the corrective action has worked. If the issue returns, the analysis needs to continue.
Why RCA matters for the Industry - and the data behind it
In most plants, breakdowns aren't down to people not caring, it's more that everyone's busy, and habits are hard to shake. When something fails, the team does what they're trained to do: fix it and move on.
The line’s running again, production continues! And for a while, it feels like the problem’s solved. Then the same fault shows up next week, and the next, and the next. Without a structured way to find the root cause, the same pattern will keep repeating, costing time, money, and trust.
The Hidden Cost of Repetition and Reactive Maintenance
Industry research consistently shows that repetitive failures, with reactive run-to-fail maintenance, are among the biggest drains on uptime and maintenance resources:
- According to an ABB global survey, unplanned downtime costs industrial companies an average of $125,000 per hour - and up to 10% of total production time in some sectors.
- Forbes Technology Council reports that across manufacturing, downtime eats 5-10% of production capacity annually, often due to recurring mechanical and procedural faults.
How to carry out a proper RCA - Best practices
The RCA process will look different depending on the RCA tool you choose to use, but the fundamentals are always the same. No matter the tool, effective RCA to figure out the cause and effect depends on a few key habits to ensure you understand the how and why a problem developed, so it doesn’t happen again.
Base the analysis on facts, not guesswork
Don’t start with assumptions, but with evidence. Gather real data: photos, readings, timestamps, operator logs, and maintenance records. If it’s a safety deviation, go to the spot where it happened. If it’s an equipment failure, look at the timeline - not just the moment it broke. Guesswork compromises a RCA because it locks you into the first explanation that “sounds right.” Real facts often tell a different story. A proper RCA starts with the question: What do we know happened?
Involve the people who know the work
Root causes live where the work happens so they should be overseen by the people who were on the job. Include operators, mechanics, or drivers who experienced the problem firsthand. They’ll catch the small details that rarely make it into reports but often make all the difference.
Look along the whole timeline
When something fails, it’s tempting to focus on when it happened. But many events start long before the actual stop, injury, or defect. Zoom out. Reconstruct the timeline leading up to the event:
- What changed in the process, staffing, or environment?
- Was there a new operator, new material, or a schedule squeeze?
- Did maintenance, inspection, or training routines shift in the weeks before?
Looking wider helps teams spot the real chain of cause and effect instead of just the final link.
Don’t stop at the first cause
This might be the single biggest difference between average and excellent RCA. Most teams stop as soon as they find a cause, but that may or may not be the surface layer. The deeper you go, the more likely you are to find a systemic issue, something built into how the work is organized. For example:
The machine stopped because a belt slipped.
The belt slipped because it was worn.
It was worn because the tensioner was never replaced.
The tensioner wasn’t replaced because it wasn’t on the Preventive Maintenance (PM) list. THAT’S your root cause - not the belt, but the system that forgot the tensioner.
Realize that there can be more than one cause to the effect
Reality is messy and sometimes it’s not just one thing, it’s two leaky pipes instead of one. Maybe a mechanical fault and a procedural gap combined at the same moment. Or maybe two departments each did the right thing individually but together created a weak point.
The point is: don’t chase a single “silver bullet.”
Using digital tools in RCA
One of the biggest challenges with paper-based RCA is that the insights get lost, findings get filed away and forgotten, and the same issue quietly resurfaces somewhere else. A digital setup keeps the analysis saved and shared, so what you learn truly gets put to use and knowledge of the learnings are retained.
Photos, timelines, and actions stay in one place, so teams can see what went wrong and what’s been done to prevent it. When learning is easy to access, it spreads, and the same mistake doesn’t repeat. It also helps build strong habits. When it’s simple to log an event or add a “why-chain,” RCA becomes part of everyday work.
How to move from quick fixes to lasting corrective actions
The hardest part is usually just getting started. Once a process is in place and people build it into how they work, it holds on its own. And getting started with your RCA process is no exception. A supporting RCA software or other tool for incident and case management can lower that initial barrier by bringing reports, evidence, investigations, responsibilities, and follow-up actions into one place.
A digital platform makes it easier to structure data, trace cause-and-effect relationships, assign corrective actions, and verify that they have actually been completed. CheckProof supports your entire root cause analysis risk management process, helping teams move beyond repeated quick fixes and turn each incident into practical improvements that reduce the risk of the same problem happening again.
FAQ - Root Cause Analysis
Want to know what CheckProof can do for you?
CheckProof's easy-to-use app makes it easier to do the right thing at the right time. Discover how you can run world-class maintenance that is both cost-effective and sustainable.
Book a demo
2026-09-29
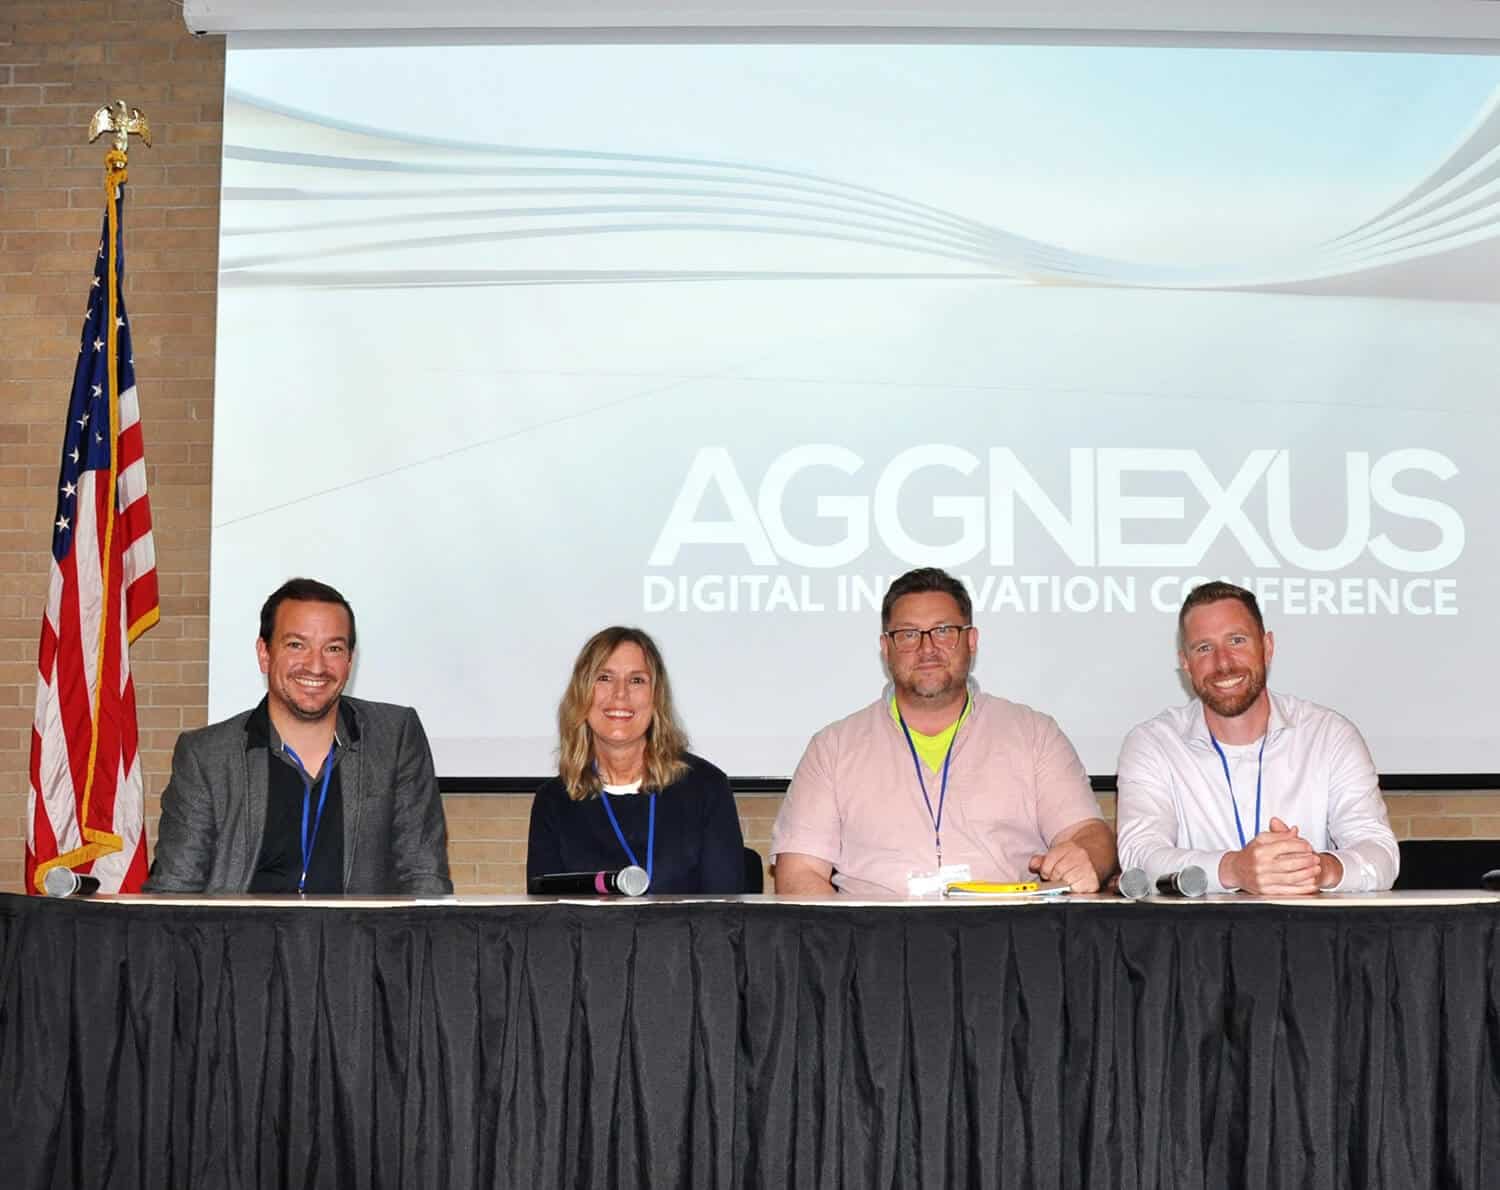
The AggNexus 2026 Report: Highlights from the Digital Innovation Conference
AggNexus 2026 in Austin was the biggest edition yet. After a year of AI first steps, the focus shifted to how to get people to change. Here are CheckProof’s key takeaways on change management, fast-moving AI, compliance and passing on know-how.
2026-09-24
Stärkere Basis: Rohrdorfer verbessert durch Digitalisierung Sicherheit und Effizienz
Rohrdorfer, ein führendes Baustoffunternehmen in fünf Ländern, nutzt CheckProof seit Jahren für Sicherheit, Wartung und Qualität. Das stärkt den eigenen Betrieb und die Kundenorientierung.

2026-07-10
10 Must-Have Features for an Incident Management Platform in the Heavy Industry
When an incident happens, every minute matters. A near miss, equipment damage, or a hydraulic leak can quickly become a bigger risk if the issue is not reported, investigated, and followed up properly. When an incident happens, every minute matters. A near miss that goes unreported, or a fault that isn’t followed up, can quickly become a bigger risk if the issue is not reported.

2026-07-09
The Benefits of a Quarry Crusher Management Software
Paper forms, scattered systems, and knowledge locked in one person’s head all delay the same thing: catching crusher problems before they become breakdowns. This piece covers the four biggest challenges in crusher operations and how CheckProof brings inspections, maintenance, and issue tracking into one place.

2026-07-06
Hillhead 2026 – The CheckProof Report
Hillhead 2026 broke every record with 627 exhibitors and three days packed with electric machinery, connected intelligence, and sustainable innovation. CheckProof was on the ground as an exhibitor and sponsor — here’s what our team took away from the show floor.

2026-06-12
Brice Aggregates: What Operational Excellence Looks Like at a Needingworth Quarry
The inaugural CheckProof Industry Excellence Award winners on going digital from the ground up, and the moment their frontline teams bought in.
2026-05-07
Why Your FMEA Is Sitting in a Binder (And What It Should Be Doing Instead)
Most facilities have an FMEA — but it’s collecting dust in a binder instead of driving decisions on the floor. Here’s how to turn your risk analysis into a living tool that actually protects uptime.
2026-04-24
CMMS Features and Functionality: What to Look for in a Maintenance Management System
Not all CMMS (Computerized Maintenance Management System) platforms are built the same, and in industries like quarrying, aggregates, cement, and ready-mix concrete, there are certain capabilities that carry more weight than others. The CMMS features that matter most for maintenance teams in asset-intensive industries include things such as centralized asset data, work order automation, preventive and predictive scheduling, digital checklists, deviation management, fleet optimization, and mobile-first design with offline capability.

2026-04-24
Cement Plant Inspection Checklist: What to Check, When to Check It, and Why It Fails
Most unplanned shutdowns in a cement plant don’t come out of nowhere. There’s usually a trail beforehand. Maybe a kiln bearing that’s been running 15 degrees above baseline for three weeks, noted by the operator on shift but never formally flagged because it hadn’t tripped an alarm yet. The issue isn’t a lack of warning, its that small deviations are often tolerated until they tip over into something serious.

2026-04-01
How to Choose the Right Work Order App for Your Industry
When something breaks on site, the fix gets most of the attention, but it’s rarely where things go wrong. What’s just as critical is everything around it: who reported it, who picked it up, what got missed between shifts, and how long it sat before anyone acted. In many operations, that whole flow is still held together by paper forms, radio calls, and memory.